Close the Loop Automatically
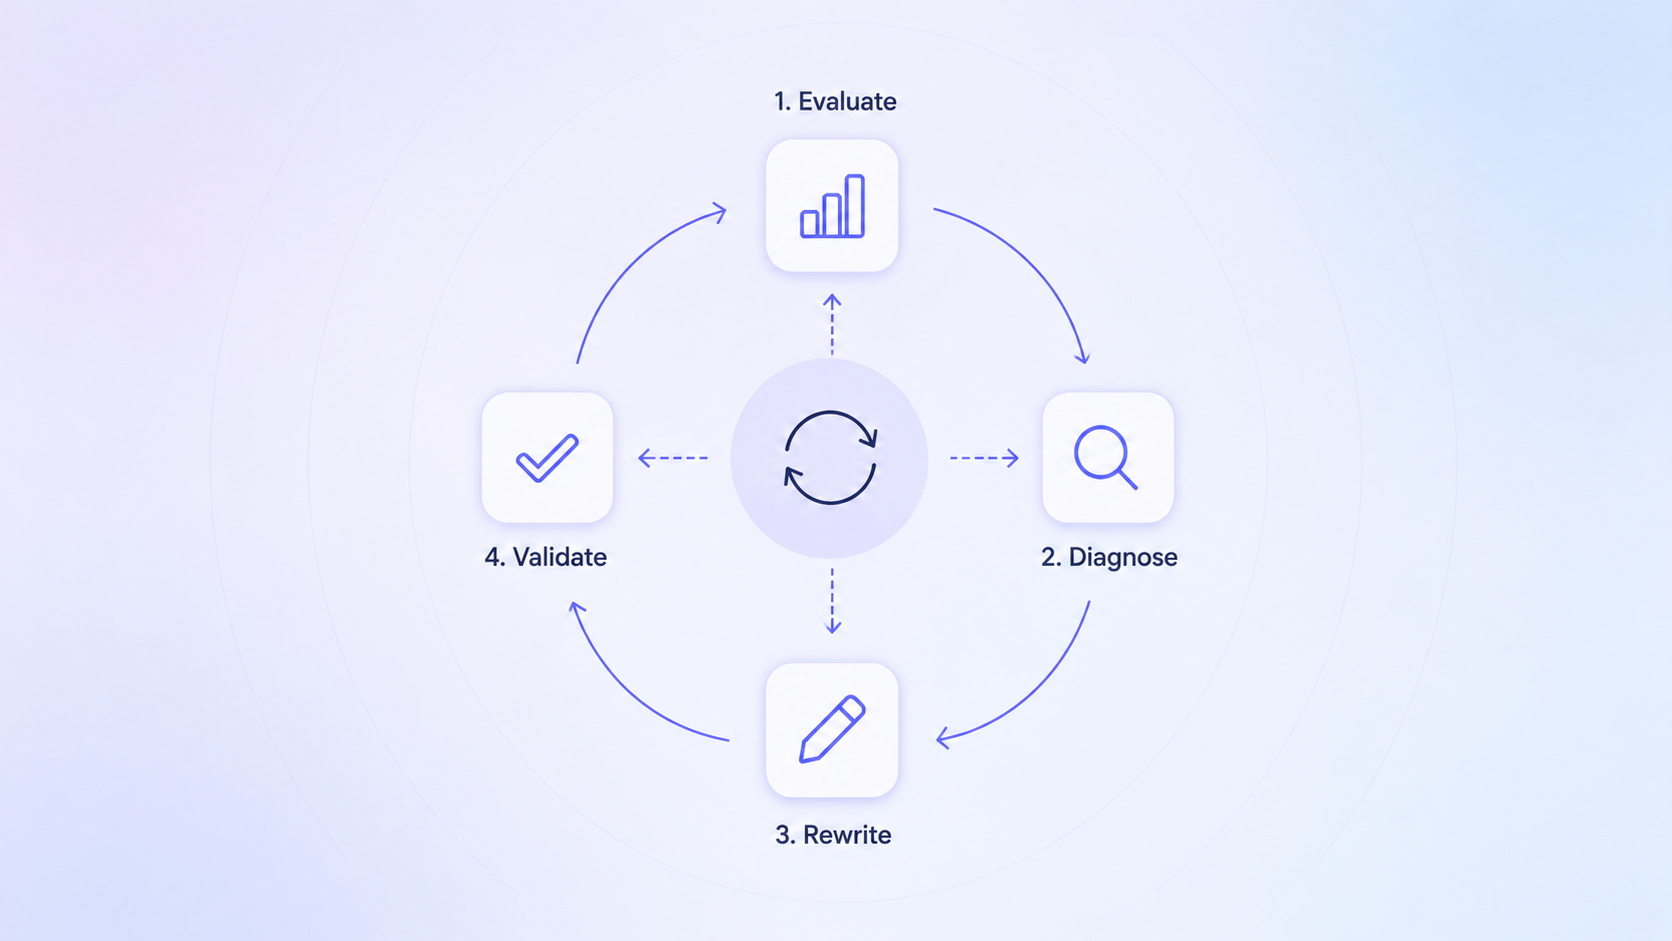
Most teams fix agent issues manually — listening to calls, rewriting prompts, re-testing. This course teaches you to build a loop that does that continuously: eval results feed into diagnosis, diagnosis feeds into prompt rewrites, rewrites get validated automatically.
Works With Your Stack
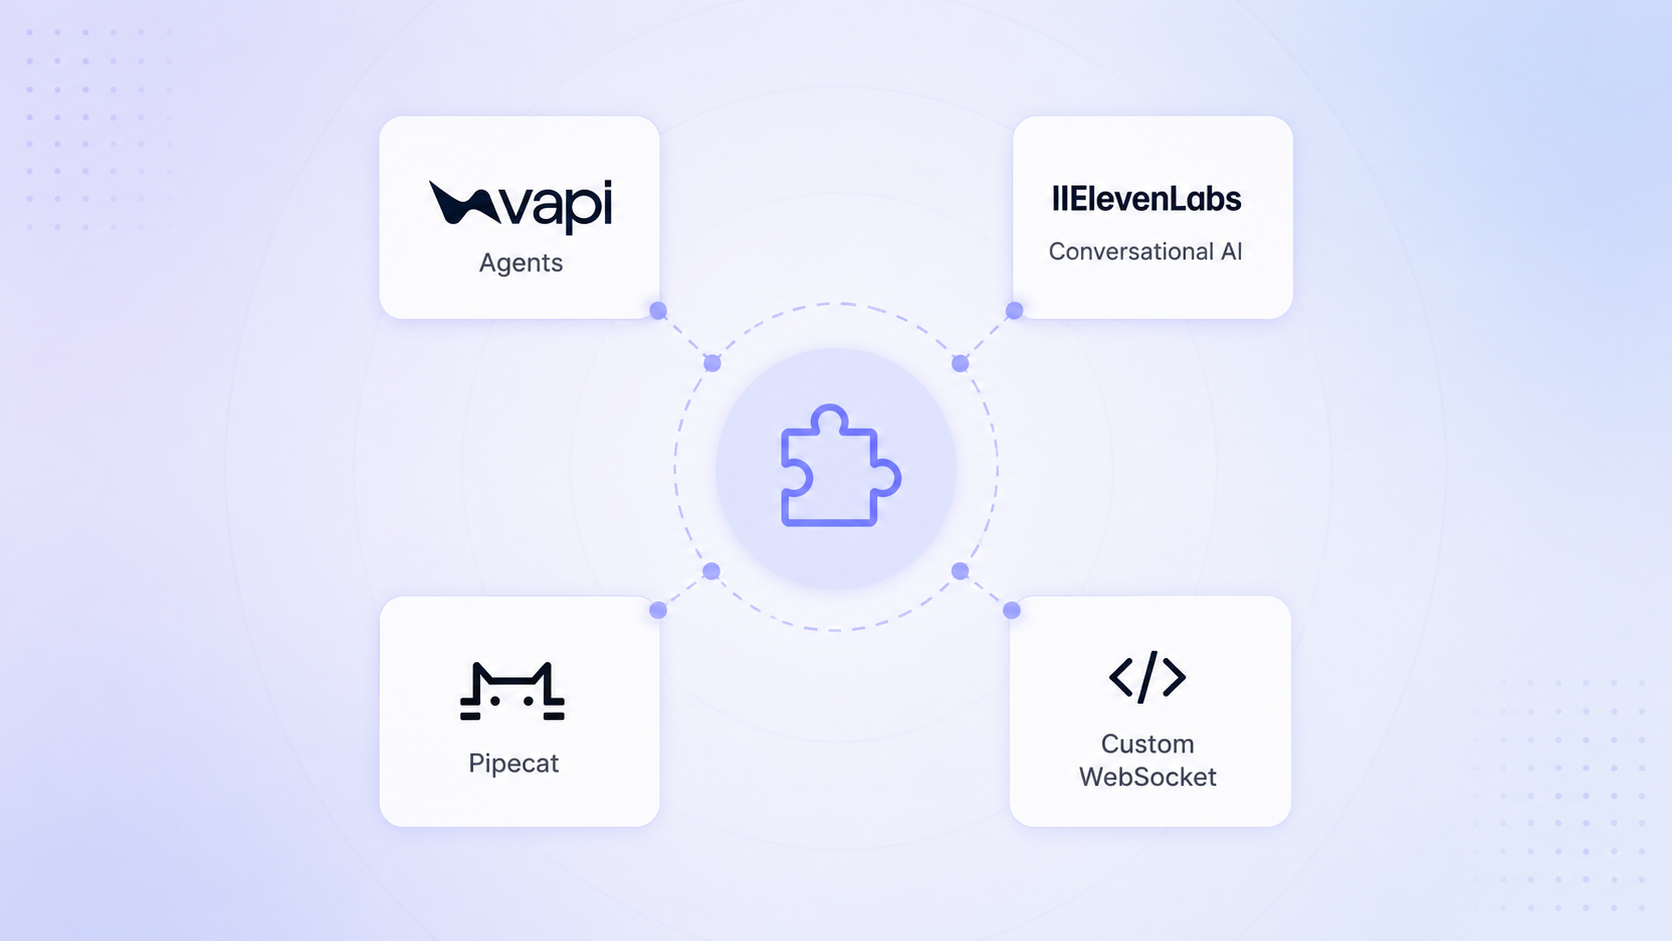
The patterns cover VAPI agents (squads + tool definitions), ElevenLabs Conversational AI, and self-hosted pipelines (Pipecat, custom WebSocket). Bring your own agent — the framework adapts.
Ship Faster, Break Less
Self-improving loops catch regressions before users do. You'll learn to set up rubrics, run batches, and surface root causes so every deploy is backed by data, not gut feel.
About the Course
Voice agents break in subtle ways — latency spikes, hallucinated tool calls, personality drift mid-conversation. Fixing them manually doesn't scale. This course walks you through building self-improving loops: automated cycles that evaluate your agent against real scenarios, diagnose failures, propose prompt changes, and re-validate — all without manual intervention. You'll go from "listen to 50 calls and guess what went wrong" to a system that tightens itself with every batch. Built by the Cekura team, based on patterns we've seen across hundreds of agent deployments.
What You'll Learn
-
-
(Included in full purchase)
Welcome to Cekura University
-
(Included in full purchase)
-
-
(Included in full purchase)
How to connect an Agent
-
(Included in full purchase)
Writing Test Cases
-
(Included in full purchase)
Dynamic Variables
-
(Included in full purchase)
Mock Tools
-
(Included in full purchase)
Running Evaluations and Reading Results
-
(Included in full purchase)
-
-
(Included in full purchase)
Folders and Evaluators
-
(Included in full purchase)
Running Test Suites
-
(Included in full purchase)
Test Generation
-
(Included in full purchase)
-
-
(Included in full purchase)
Observability and Ingestion
-
(Included in full purchase)
Predefined vs Custom vs LLM Judge Metrics
-
(Included in full purchase)
Workflow Metrics and Accuracy Loop
-
(Included in full purchase)
Alerts and Dashboards
-
(Included in full purchase)
-
-
(Included in full purchase)
Cekura MCP No-UI
-
(Included in full purchase)
Skills Demo
-
(Included in full purchase)
Self-Improving Agent Loop
-
(Included in full purchase)
Ready to Level Up? Start Today.
Get the exact framework Cekura uses to help teams ship better voice agents. No cost, no fluff, just the patterns that work.